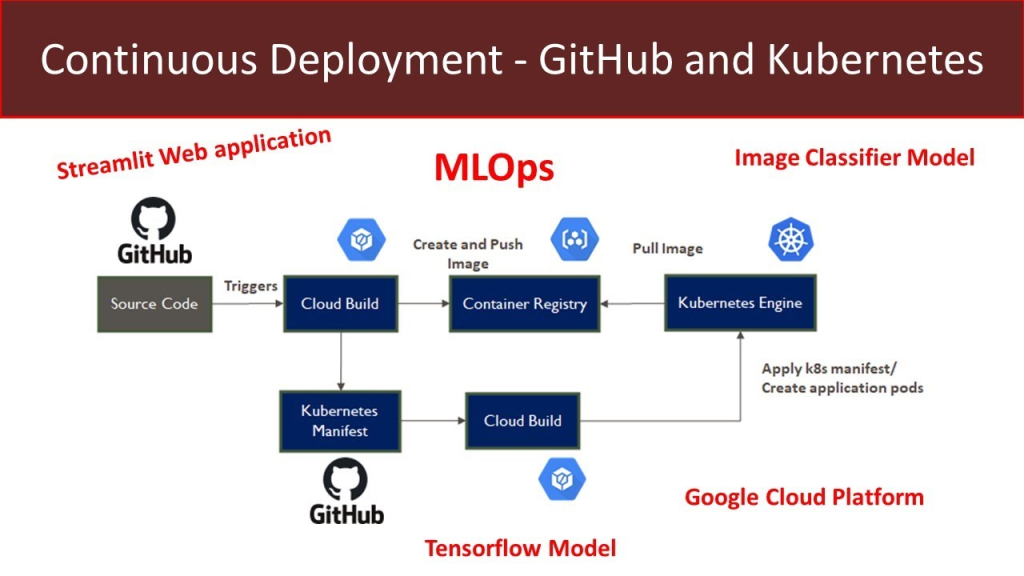
Machine Learning Operations (MLOps) is a crucial aspect of modern data science. It involves the integration of various tools, techniques, and processes to streamline the development, deployment, and maintenance of machine learning models. Kubernetes, on the other hand, is a container orchestration platform that allows you to manage and scale your applications seamlessly. In this article, we’ll explore how to implement MLOps using Kubernetes and the benefits of doing so.
Understanding MLOps
Before we dive into the specifics of implementing MLOps using Kubernetes, let’s take a moment to understand what MLOps is all about. MLOps aims to bring the same level of rigor, structure, and automation to the development and deployment of machine learning models that has been applied to software development for decades. MLOps enables data scientists to build, test, deploy, and monitor machine learning models in a systematic and efficient manner.
Benefits of Implementing MLOps Using Kubernetes
Now that we have a basic understanding of MLOps, let’s explore why Kubernetes is a great platform to implement MLOps.
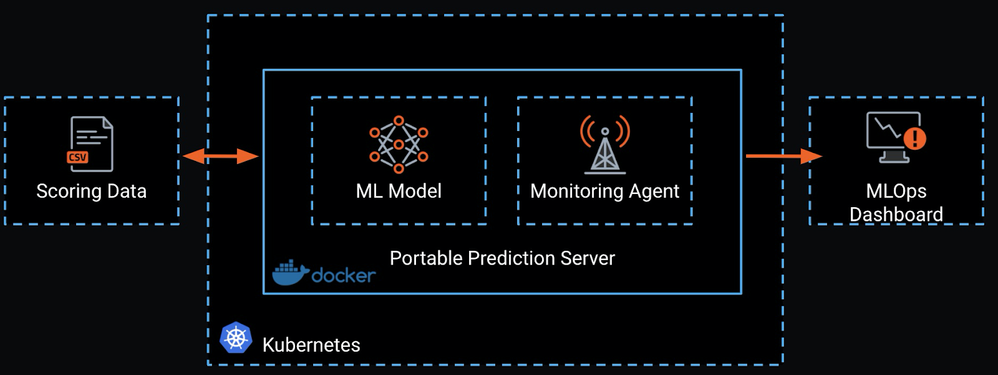
Scalability
Kubernetes is ideal for managing and scaling containerized applications, which makes it a perfect fit for machine learning models that require a lot of computing power. With Kubernetes, you can easily scale up or down your machine learning models based on the workload.
Portability
Kubernetes provides a consistent and portable environment for your machine learning models. This means that you can deploy your models on any Kubernetes cluster, regardless of the underlying infrastructure.
Automation
Kubernetes enables you to automate the deployment and management of your machine learning models. This means that you can focus on building better models, rather than worrying about the infrastructure.
Resource Management
Kubernetes provides powerful resource management capabilities, which allows you to optimize the performance of your machine learning models. With Kubernetes, you can allocate resources to your models based on their workload, which ensures that your models are always running at optimal performance.
Implementing MLOps Using Kubernetes
Now that we’ve covered the benefits of implementing MLOps using Kubernetes, let’s explore how to actually do it.
Step 1: Containerize Your Machine Learning Model
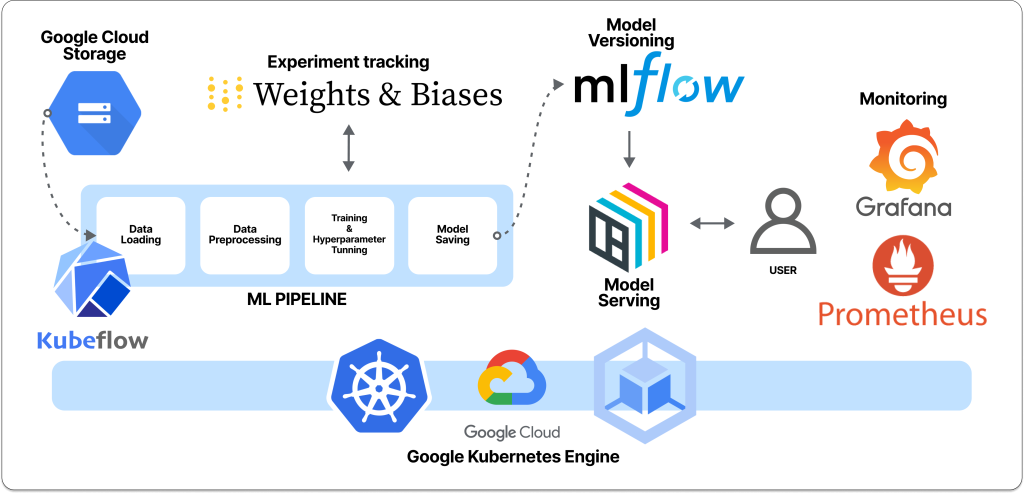
The first step in implementing MLOps using Kubernetes is to containerize your machine learning model. This involves packaging your model and all its dependencies into a container image that can be deployed on a Kubernetes cluster.
Step 2: Create a Kubernetes Deployment
Once you have containerized your machine learning model, the next step is to create a Kubernetes deployment. This involves defining a set of instructions that tell Kubernetes how to deploy your containerized model.
Step 3: Create a Kubernetes Service
After creating a deployment, the next step is to create a Kubernetes service. A service provides a stable IP address and DNS name for your deployment, which enables other applications to communicate with your model.
Step 4: Monitor Your Machine Learning Model
The final step in implementing MLOps using Kubernetes is to monitor your machine learning model. This involves setting up monitoring tools that track the performance of your model and alert you if anything goes wrong.
Conclusion
In conclusion, implementing MLOps using Kubernetes offers numerous benefits, including scalability, portability, automation, and resource management. By following the steps outlined in this article, you can containerize your machine learning models, create Kubernetes deployments and services, and monitor your models for optimal performance. By doing so, you can streamline the development, deployment, and maintenance of your machine learning models, and focus on building better models that deliver real value.
