In the context of database operations, “truncate” and “delete” are both commands used to remove data from database tables. However, they differ in their behavior and impact:
- Truncate: The “truncate” command is a Data Definition Language (DDL) operation that removes all the data from a table while keeping the table structure intact. When you truncate a table, it deletes all the rows within the table, but the table itself remains with the same columns, indexes, and constraints. Truncate operations are typically faster than delete operations because they do not generate individual delete statements for each row. However, it is important to note that truncating a table cannot be undone, and it does not trigger any database triggers or fire any associated delete events.
- Truncate is a non-transactional operation, meaning it cannot be rolled back. Once you truncate a table, the data is permanently deleted.
- Truncate resets the auto-increment counter for the table, so the next inserted row will start with the initial value.
- Truncate removes all data from the table, including indexes and constraints. However, the table structure remains intact.
- Truncate is commonly used when you want to quickly remove all data from a table without the need to specify specific conditions.
Example:
TRUNCATE TABLE users;- Delete: The “delete” command is a Data Manipulation Language (DML) operation that allows you to remove specific rows from a table based on certain conditions. Unlike the truncate command, delete operations can be conditional and selective. You can specify criteria in the delete statement to determine which rows should be deleted. When you delete rows from a table, the corresponding data is permanently removed, and the affected rows are no longer available. Delete operations generate individual delete statements for each row being deleted, which can be slower compared to truncating for large tables. Delete operations can also trigger database triggers or fire-associated delete events.
- Delete is a transactional operation, meaning it can be rolled back within a transaction. You can wrap delete statements within a transaction to provide atomicity and consistency.
- Delete can be selective, allowing you to specify conditions to determine which rows should be deleted. For example, you can delete rows based on specific values, comparisons, or patterns.
- Delete affects only the rows that meet the specified conditions, leaving other rows and the table structure unaffected.
- Delete generates individual delete statements for each row being deleted, which can cause performance overhead for large tables or complex conditions.
- Delete can trigger database triggers or fire-associated delete events, allowing you to perform additional actions or maintain data integrity during deletion.
Example:
DELETE FROM users WHERE id = 1;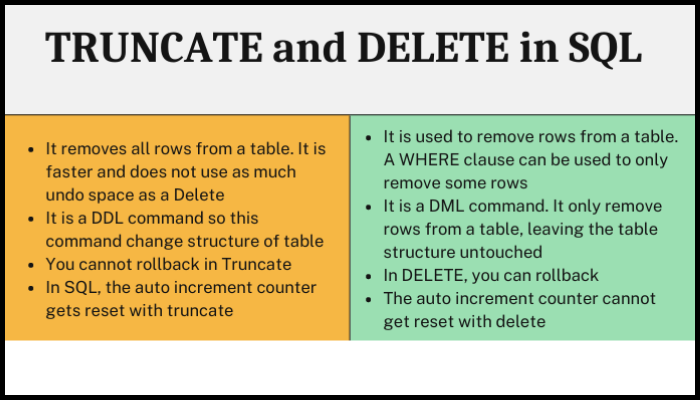
In summary, truncate removes all data from a table while preserving the table structure, whereas delete allows you to selectively remove rows based on specified conditions. Truncate is faster and cannot be undone, while delete provides more control and triggers associated events. It’s important to use these commands with caution, as they have a permanent impact on your data. Always ensure you have proper backups or take necessary precautions before performing these operations in a production environment.
